Section Insights
Introduction to Skill Induction
What is the focus of today's lecture?
The lecture focuses on how agents can store information across tasks in external stores to improve future performance, emphasizing skill induction and the complementary nature of skills and instructions.
- Agents can retain information within a context window to enhance task performance.
- Skill induction allows agents to store and utilize knowledge from past tasks.
- Human input can refine agent-generated skills and instructions.
Implementing Agent Skills
How are skills structured for agents?
Skills are implemented as collections of files, including a mandatory skill.md file that contains metadata and detailed instructions for the agent on how to apply the skill.
- Skills are stored as structured files that agents can read.
- The skill.md file includes essential metadata and application guidelines.
- Optional resources can enhance the agent's ability to execute the skill.
Improving Skills Through Experience
Why is it important to base skills on past experiences?
Basing skills on past interactions leads to better performance, as agents can learn from previous tasks rather than relying solely on initial task descriptions.
- Agents perform better when skills are informed by prior experiences.
- Human oversight can enhance the effectiveness of agent-generated skills.
- Continuous evaluation of skills through real-world applications can lead to improvements.
Challenges in Skill Representation
What are the potential issues with representing skills?
Skills may break if the underlying elements change, such as when element IDs on a page are modified, highlighting the need for adaptable skill representations.
- Skills must be adaptable to changes in the environment to remain effective.
- Comparing text and code representations can reveal strengths and weaknesses in skill design.
- Historical research lays the groundwork for developing robust skill induction methods.
Benefits of Code in Skill Induction
What advantages does using code provide for skill induction?
Using code allows for more structured skills, reduces the need for frequent environmental interactions, and enables the agent to execute tasks more efficiently.
- Code-based skills can streamline task execution by reducing repetitive actions.
- Feedback mechanisms can enhance the quality of skills through iterative improvements.
- Induced code skills can significantly increase the speed and efficiency of task completion.
Transcript
0:01 Okay, welcome back everyone. >> So, the first assignment is out and as Graham said, we we have credits available for you to to work on it for those of you who are enrolled in the class. Do you folks have any logistic questions? Cool. Okay. So we talked in the last lecture about how agents can choose what to retain within their context window as a way of you know storing information within a task and using that to to determine what's important to do better within the task.
0:36 So a big part of today is going to be about how can agents go beyond the context window and store information across tasks in external stores that will be useful for them to improve performance on tasks in the future. And this is going to be skill induction. and we'll build on some some work that was done in the past on memory systems for agents. and show how to apply those to to agents. But there's also another view on skills. And skills are a way for people to write instructions for an agent that can encode kind of like best practices or the knowledge that you have about how a task should be done. And these are actually going to be complimentary to each other. so we'll cover it just a small amount in this lecture but you can imagine a system that is sort of having a human in the loop that's relying on the agent to propose some potential best practices from the experiences that it has a person edit those and goes back and forth or vice versa like you know having a skill and instruction that's written by a person be refined by the agent based on experience. So yeah, it's a lot of different viewpoints, but hopefully by the end of the lecture, you'll see how they can all sort of fit together.
2:00 So let's just start off with some motivation about why you might want to remember things from one task to another. So say that we have an agent that's carrying out tasks in a website like a shopping site and you might give it a task like add Sony headphones to my wish list. So when we cover guey agents, you'll we'll get into the details of, you know, the representation space, the action space for how a system like this works. But at a high level, it's going to be producing actions like navigating to the store website, finding the search box for it, typing some text in that search box, and then clicking search. And that's going to be the part that like searches for the headphones, right? And then we'll do something with them. We'll find the ones that match the request the user had and put them into our wish list.
2:51 We might have another task that we carry out in the future like find the wireless keyboard price range. And if we're doing that on the same site, a lot of the actions are going to be reused, right? We'll go to the store, we'll find the search box, we'll search for the different product but in a similar way and then we'll do something different with it like you know getting the prices and reporting those back to the user.
3:13 But if it's difficult for the agent to figure out how to do this search, once it knows how to do it, it should be able to reuse that knowledge in the future to be more effective on future tasks. So a lot of structure recurs and today is going to be about how can we represent this shared structure. So for example, is it best to just keep kind of the raw actions that the agent produced when it was carrying out this shared subtask or is it better to try to abstract it into for example a code function which could be run as a blackbox or maybe tested or even like hierarchically call other functions.
3:57 We'll also be interested in how can the agent like determine which parts of a task should be reused in the future. And as we're you know any time we have a memory that we're building up from experience, there's questions about how do we grow that memory? Do we are we always adding to it? What happens if we get some conflicting information or we find a better way to do something? We might want to make edits to it. we might want to delete things if they no longer seem to apply. So, how can we kind of manage the life cycle of these skills and these subtask representations that are learned?
4:40 So, I'd say there's three general ways that we can get agents to update. So, the first one we covered in the last lecture. It's just what you maintain in the context window of the model. So this is you know in the standard React style way. It's the history of the past observations and actions that you've taken, messages you've gotten from the user, feedback from the environment, and you need to you need to choose like what to retain given kind of the limitations of the context window and the model's ability to use that. So we talked a lot about like compaction and methods for managing what's in that context window. Today we're going to be focusing on storing things outside of the context window. So even with like really long context windows that we have now of like a million tokens for multiple for like carrying out multiple tasks with an agent you're going to exceed that context window and you want to remember things from past tasks to help you on future ones. So if we are storing things outside of the window, that's going to look something like a database that needs to be managed in some some way or like a file system that the agent can access. And this lecture is going to be about methods for putting things into those types of storage and using them and updating them. And then the final way is going to be like actually making updates to the weights of the model.
6:12 Right? So this looks more like standard supervised fine-tuning or reinforcement learning. We'll cover that in a few lectures later on. But each of these has like pros and cons. So I think like a main pro of using external artifacts is that they're like they can be ported across models, right? So if you have a description of the way to search for a product that could be used by any one of a number of different models within an agent framework. Whereas if you're actually making updates to the weights of the model that's just an update for that specific model and it doesn't transfer to others. So external artifacts are also more inspectable by people. so you could write down best practices or how to search on a site.
7:02 The agent can use that. The agent could also propose, you know, kind of text for that and you could look at it and make changes to it. So there's it's easier to kind of like have an interface between the person and the system if your method of updating, if your method of remembering is interpretable. Any questions about this? How many folks have have used skills in their interactions with the coding agent? Like how many of you Okay, so most folks have. How many of you are are writing the skill yourself?
7:36 Okay, so maybe about half the folks who are using skills. How many of you have gotten an agent to write a skill for you? Okay, so a lot of folks actually have. Yeah. What are some things that what how what's your experience been for the agent writing the skills? How often have you been able to use it just right out of the box? The thing that the agent constructs anyone have any spectacular failure cases or spectacular successes? So just repeating that for the recording like sometimes the models will write too much in the skill like they'll kind of overinfer the what should be done and then when that's handed off to another model it will kind of follow it to the letter and do a lot more than you actually wanted it to.
8:22 >> Any other examples from folks? >> Cool. Oh yeah, go ahead. I mean in cases when you're like trying to like a production issue for like a particular system if you give it like three or four support and you tell it that look at how people have this issue in the past create a skill for yourself other agents could use to it in the same way >> and that's very >> oh nice >> okay cool yeah so instructing it to like get write the instructions for another agent it's good enough it's sort of like simulating what the agent would do.
9:00 Yeah, that's interesting. I've sometimes found that the models are like pretty bad at kind of like simulating the theory of mind that you know another person or an agent would have when they like look at instructions, but they get a lot better when you prompt them to do that. Cool. Okay. Yeah. So, a few different like types of experience that we might want to retain for agents. So the first is like the episode and this is you know just the sequence of observations that you get from the environment from the user and the actions that are taken and this is sort of like the maximum fidelity right you're just you're retaining everything you have all the specifics of that particular environment and the particular instructions that the user gave also going to be like the most costly right it'll need the most tokens to represent and you probably don't need all of that right? just like when we're doing you know supervised learning we don't want to retain every detail we want to abstract to the things that matter to generalize in the future.
10:06 So we could also retain some facts like some knowledge about the environment or about the user and in the early work on memory systems a lot of it was focused on retaining facts. So like a user is interacting with an assistant and maybe gives some personal information like how old they are or where they live. The system can retain that in its memory and then use that fact to improve future interactions. If you've used like Anthropic or Chatbt's memory systems, they're doing this basically, right? Like you can go into the settings, you can view the memory that they have about you and there's, you know, a text representation there from a model that's produced those facts from your past interactions.
10:55 Looks a little bit like compaction in some way. It's generated by an LLM. It gets stored in this external thing. And then the final one is more specific to agents. So it's about like how do you do part of a task in a way that's abstracted from the details of the task. So like in the example we looked at before, how do you search for products on a particular website without maybe retaining the details of searching, you know, the particular product that you searched for? And so there's a lot of choices about how you would represent a skill. Is it just text? Is it kind of the actual actions that you took? or could it even be code?
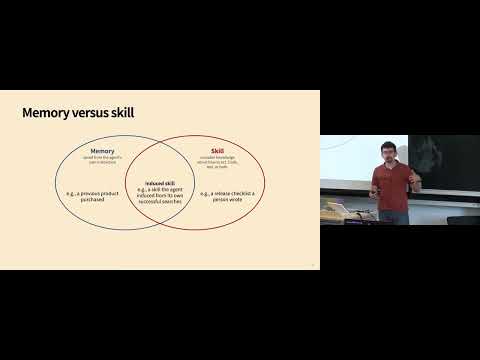
11:35 And of course, skills are only going to be useful if you're going to be doing the same subtask more than once. So we could think about like memory and skills and the intersection between them. So memory is just something that we're saving from the agents interaction. So for example, what's a previous product that you purchased on a site? A skill would be reusable knowledge about how to act in an environment. which could be represented in one of a variety of ways.
12:06 Like it could be, you know, if you're releasing a application by pushing it to production, here's a checklist that you need to go through before you do that. So, a skill could be written by a person like in this example. But we could also have a combination of memory and skills. So we could induce skills from the agents past experiences and store those and then use those to hopefully do better in the future. So if the agent searched successfully for a product in the past and yeah and if it was successful, if we think that it was successful, then we could pull out something that looks like a skill to guide the agent in the future. And we'll get a lot more concrete about what this looks like through the rest of the lecture.
12:54 So we can think about skills as instructions where skills as instructions might be written by a person for encoding their own you know preferences or might be organization policies like this is the way that we write and test code in this particular company. and human authored skills we know where they came from. we have more maybe control over the quality but it takes you know a lot of time to write them and to maintain them. If we're learning skills then the agent is producing them. and this is helpful because we can do this in an automated way. Maybe we can have like a loop where we induce the skill.
13:34 We try to use the skill to redo the same tasks. We see if things get better on a metric. but it can be, you know, potentially noisy too and have, you know, especially if you're using the skills for some other agent like we talked about in those examples everybody gave, it could maybe have unintended consequences too. Okay, so let's talk first about humanridden skills and the standards for these and the ways that they're used in incurrent agents. So probably a lot of it sounds like a lot of you have experience with this already. so maybe you've been using these in the context of an example kind of like this.
14:15 there's this nice blog post from open hands that has guidance on using skills. for those of you who who haven't used skills yet or if you you know like some suggestions on how to how to have best practices for creating and using skills. But they have this motivating motivating example of say that you find yourself like always giving similar instructions to a coding agent. so you want the you want to check the code that has been written using one of a couple different llinters. You want to give type hints.
14:49 You want to use a particular type of dock strings. And you want to apply piest to all the functions. So if you're always doing this, you could always type this guidance into the system. but you know, a kind of natural and faster way to do this would be to just have the like store the guidance as a text file and then have the agent use that guidance as an instruction. So you should reach for a skill when you want to do something repeatedly following kind of like a fixed specification. And the agent's going to choose how to interpret this specification in context, but the general instruction is the same.
15:31 And the way that this is implemented in the current standard for skills which is called agent skills is just as a collection of files which the agent is able to read. And here's an example of of that. So if we are constructing a skill for Python review we'll have a folder which has a structure like this. So skills have this standard structure where they'll have a skill.md file and you have to have that. Skill.md is a markdown file that starts with some YAML metadata. So you need to have a name for the skill and you need to have a short description which is going to give guidance to the language model about when the skill should be applied. And we'll see in a slide or two about how the model gets access to this information in the YAML header. And then after the header you'll have a much more detailed description of how the skill should be applied which would for example you know list here are all the llinters that you should apply here's how testing should be done and so on. So you have to have skill.mmd. You also have a few other folders which are optional but can contain some extra resources for the agent to use as it carries out the skill. So there's scripts which has executable code. So for example, if you had like a Python script that would run a llinter, you could put it in there and then describe it in this skill.md file. There's also references, which would be sort of like supplementary documentation that maybe you don't you you don't need to use it every time you use the skill. but you'll have maybe a reference to that documentation in the skill file. The agent could load it as needed from the references folder. And then assets basically just has like, you know, additional templates or resources like if you're, you know, doing something that involves like Ginga and you need the agent to load that conditionally.
17:32 So this can be a lot of information, right? And we don't want to fill up the context window of the model with all of the possible skills that it could use. So there's a mechanism called progressive disclosure which is going to just show relevant parts of skills to the agent as they're needed. So the first level is the metadata in this YAML file. so the name and the description and that's always going to be shown to the model in the system prompt if the skill is loaded if it's available to the model to use. So you need to be kind of concise in this description. so that if you have a lot of skills you don't fill things up too much.
18:19 There's the second level which is the rest of the text in the markdown file and that'll be loaded conditionally if the model decides that the skill is relevant and decides to read the rest of the file via a tool call. We'll see an example of that in a minute. And then the next level is sort of like all the resources in here which will also be loaded using tool calls. So you kind of need to have enough information in the skill.md file for the model to be aware that it should look into these additional folders to get more resources when it's carrying out the skill. Any questions about this and you'll implement this in assignment one or maybe some of you are already starting on implementing that.
19:05 >> Yeah. are so high like what if that takes too much of that effect performance? >> Yeah. So if you have a lot of skills even if the skill metadata is pretty short could it affect performance? Yeah, it definitely can. so you want to keep the number of skills somewhat small and maybe just load them conditionally.
19:36 in one of the state-of-the-art agents, Hermes agent, I think the I'm not sure the number of skills, but like the total length of the skill descriptions in the system prompt is like 3,000 tokens. there's some papers that we'll see in a little bit that show that if you have too many skills, it can make performance worse. Like adding in irrelevant skills can drop performance because, you know, the context gets longer. The model might be distracted by things that are actually irrelevant. So yeah, you definitely need to be careful about the number of skills, but I think it would be pretty rare to have like 10,000 or a thousand skills. Generally, it's, you know, smaller and you would maybe load skills as needed for like the software tasks that you're carrying out.
20:19 >> Yeah. >> How sensitive are those triggers? >> Yeah, that's a great question. How sensitive are the triggers? So the the triggers will be tool calls that will be generated by the model. And so whether they get called or not is a function is totally dependent on the model. and you know the model's ability to predict that it should be triggered based on the past context and what it knows about the skill. So that you know depends on the model depends on the description you write and that's why we need evaluations for this. and one of the papers that we'll look at takes a step in that direction.
20:59 >> Yeah. like a standardized name. >> Yeah. skill.md is a standardized name. So the the standard is called the I think the agent skills standard and you like models agents are trained to to use that agent frameworks are trained to load that. so yeah you if you want to use an alternate format well first put it you know as close to this as you can but you could do you know if you have particular if you have particular things that you want like in the references folder you could describe them in skill.md and like all this is just going to be instructions to the language model so it could be robust to other configurations also especially if you describe them.
21:50 >> Yeah. Why are >> Yeah, why markdown? It it is a balance of machine and human readability, I think. >> Yeah, that's a great question. Could there be better formats than than skill.md? Yeah. Do you have things in mind? I think like so I mean it's just like linear right it's you can have hyperlinks which is good you can embed images too >> yeah but like it's difficult to you know represent things that are dynamic so like maybe you want to illustrate to the model like different ways the data could be visualized you know maybe that would be better with like a JavaScript interactive JavaScript application or something like that. yeah, you could, you know, have that be sort of like a code file here that gets executed. but and maybe like referenced in the markdown. so I think like markdown is sort of the best attempt at having something that's general and like readable, but then you would rely on the language model to interpret other formats.
23:10 >> I think in the scientific literature that Daniel's going to talk about, there's basically two ways. There's textual skills and programmatic skills and the textual skills appear in the markdown and the programmatic skills appear in the script. So it kind of it's pretty broad if you consider those. >> Yeah. Cool. >> Yeah. >> Does anyone do to not have to put it all in context? For example, if you're making an agent that modifies cloud infrastructure, you work at some big bank and have a billion things in AWS and it would be nice to be able to just ask the model to modify something, but then because it's a billion things, you can just have a billion tools for every small component available. Yes.
23:54 >> So looks like something would do. Yeah, definitely in some of the research papers that so the question was like do people retrieve from large collections of skills. and yeah definitely in some of the research papers that we'll look at they do that either using you know just like a text embedding based retrieval or doing something that's more kind of like domain conditional like we know these skills apply to this site so when we're interacting with that site we'll load those skills. Yeah, I imagine production systems do this too, but yeah, I don't have any references off the top of my head for that. Cool. Okay, so we'll just kind of quickly to show you how progressive disclosure works. we first need to give the model access to this level one, right? Let it know what skills are available. And you'll have a system prompt that looks something like this. This is just taken from Hermes agent which is sort of like a standard open- source agent that is able to use and induce skills and you'll kind of describe what skills are. you'll tell the model about this skill view tool which it could use to read the rest of the markdown file and then you'll list out all the skills that you have.
25:14 So there's just two skills here. there's a code quality skill and a workflow skill. And that's just the YAML metadata from those skill files. So, the model is able to use tool calls to, you know, expand the rest of the skill. And here's what that might look like. So, it always has the index of skills in the system prompt, but it could choose to make a tool call to open the Python review skill. if that seems relevant to you know the user asked for a review of some Python code and then it's going to like you know get that markdown file insert it as a message to the system as an observation the result of that skill view tool.
26:01 the system might choose to run something from the scripts directory and then it'll get the result of running that script as an observation put it in the window and might choose to you know like view additional files within that skill package. Okay. So yeah, we these questions that we had about like you know could additional skills hurt are skills being triggered in the right place. we answer questions like this by building evaluations and the the work on this is a little bit new. It's sort of ongoing but a really great first effort in the space is called skills bench and what they do is they collect a bunch of skills from various sources online. they actually get like 2 million skills. and they'll also have people write tasks which seem like they could benefit from skills. and so they'll like get 400 tasks and those are going to be written independently from the skills, but they'll have the task annotators choose from this pool of skills ones that seem like they could apply to the tasks. And so you'll have kind of like a small set of curated skills. and you'll supply those skills to an agent as it's trying to solve the task and they'll evaluate this on like you know four different agent frameworks with I think like 18 models something like that and they'll just see like does having the skills improve performance over not having the skills across all the tasks for a given agent framework and model combination right so this will evaluate you know it'll implicitly evaluate the skill quality but will be designed to evaluate is a model and framework able to you know use the skills appropriately and they're trying to choose the skills. So they have like a filter which checks to see that for a small subset of models the performance on the tasks does improve when you give models access to the skills and then you're seeing if that's also true for kind of a wider set of frameworks and models.
28:15 Yeah. Does the general setup make sense? Cool. So on average, you know, with this cur curated set of skills, the average pass rates on these tasks using like humanridden verification criteria does increase. And so you can see like the solid bars to the shaded bars across a bunch of different models and frameworks. but actually ski like tasks that require fewer skills to solve benefit more from having the skills available than ones that require more skills. and so this is partly a difficulty thing but also partly that the models might be getting distracted by having more skills available. And you could imagine that it's getting much worse with like a much larger number of skills. we'll see some more evidence for that later on in the lecture.
29:12 And actually skills still hurt on a number of the tasks for particular model types. so the model might be using the skill inappropriately which could actually make it do the task in a way different than what the person specified. So this kind of motivates the importance of like checking to see if the skills that you wrote are actually making your outputs better. So skills can come from, you know, a bunch of different sources. They could be bundled with the harness. they could be written by a person. and a lot of you have done this, it sounds like, and you then, you know, kind of install it in a in a way that's specified by the framework that you're using, but they can also be created by the agent. And, Hermes has a skill manage tool. open hands as a skill creator command that help work you through the process of creating a skill.
30:06 And when you're creating a skill, I think it's really important to base that skill on some prior interactions that you've had rather than trying to just do it sort of a priori. and actually there's some results in the skills bench paper that show that models when they're tasked to create a skill by themselves just based on a task description, they're really bad at it. and it actually makes performance worse. So, as a person, you're probably better because you kind of like know the way that you want it to be done, but it's generally best to base it on, you know, past things that you've done because when you're doing a task, it'll reveal some things about the way you want it to be done that you might not know in advance.
30:47 So there's a nice case study of this from the open hands blog post on how do you like so you have this code review skill that you've created. How do you check and see if it's working and then improve it if necessary. So this is focused on like reviewing poll requests and what what you could do is like after the review is produced by the agent then a person is going to go through the poll request and look at each of those review comments and either address them or not. And you can apply a modelbased judge after that and count up how many of these were like actually used by the person which will give you a sense of how good the pull request was.
31:30 And you can like do this over a large number of pull requests that were created and then reviewed by the agent using this skill. And if you do this over you know like hundreds or thousands of examples, you'll get a lot of evidence about what's working and what's not, you can summarize all of that with a reasoning model and use that to like for example identify that it's not helpful to you know produce code that ignores the repo conventions.
32:00 people did like incorporate those changes quite a bit. And then you could like have the model propose some updates to the skill file that will make the you know reviews produced by the system more likely to be incorporated by the person. Cool. Any questions before we move on? Okay. So next we'll talk about how do we get models to automatically remember things from their past experience and then we'll use that to like build on to talk about inducing skills from experience.
32:40 So this is this is an old paper. This is from 2023 but it was pretty influential. and it's it's one of the first papers it's called MEMGPT. It's one of the first papers to introduce a way that you can manage memory outside of the context window of a language model. So this is like a really a systems inspired paper. I think we talked about a couple lectures ago about you know kind of having like memory hierarchies like you know something that is fast to access which for the language model is the context window and then something that's like larger but but slower and in this setting that would be like an external store of of facts and back when this paper was written a few years ago context windows were even shorter like you know 8,000 tokens so this sort of approach was really well motivated even for just interacting with like an assistant system. nowadays you know our context windows are larger but what you want to store in them is also much larger. So this sort of approach is pretty well motivated for agents too.
33:48 But the basic idea here is that you're going to have like a you'll have you know the system instructions which don't get updated. you'll have a working context which is going to pull things from an external memory and also you'll be storing things to this external memory and those reads and writes are going to be controlled by tool calls from the model and you'll also you know have like a separate storage for the actual messages that the system received but that's going to be controlled in a pretty similar way to this this memory over fax So, what this actually looks like, sorry it's a little bit hard to read with the brightness in here, but like if you you might have an interaction with the model where the user like mentions six flags and the system could produce a tool call that searches within this storage for past mentions of six flags from its past interactions. It'll take those and it'll put them into this like working context. and then the model this working context is stored within the context window of the language model. So the model will be able to use those as it outputs its response.
35:06 But it's important to be able to do more than just like add to memory because for example like maybe you're talking to the system about your job. you say I work at X, but then if you change jobs later on, you want the system to be able to like use the latest information. And this paper called me zero introduces a way for memories to be updated as well. so the way that this works is you'll have like messages coming in and each time you get a message, you'll apply a language model to extract some memories from it.
35:45 some like potential facts that you might want to store or update and you'll have an external database store and you'll try to check and see do I have anything in that database store that's relevant to these facts that I pulled out of these messages. So you'll retrieve the top K and to do this you'll use like an embedding based retriever model like you know the ones we talked about a little bit ago. you'll pull out similar facts like six flags for example or like I work at X and you'll apply a language model to check for all of these extracted memories from these latest messages do they are they present in these similar retrieved memories? If they're not present then we should potentially add them in. if they are an update to something that's there, we should replace what's stored for that with the new thing. If it negates something that's already there, like for example, you say, "I work at X," but then later on you say, "I got laid off," you might want to just delete that fact rather than than updating it. or if it's not relevant at all, you would just ignore it.
37:01 And I'll refer you to details or for the paper for for details about this because the details also change with with agentive systems but I think the idea that it's useful to be able to like update knowledge as well if you have conflicts is potentially pretty useful. So, does anybody remember something from the lecture on context management that had a similar goal to this being able to update or delete memory?
37:31 Yeah. hashing. >> Yeah. Yeah. Basically, does anybody remember the specific paper? Yeah. Yeah, it's hashing in the sense that there we had like key values and queries, right? and we were like storing values which were vectors. here we're storing like text as facts. Yeah. So the Delta paper actually did this, right? linear attention is only able to append values to your what's effectively your memory but Delta like effectively retrieves things that are stored for particular queries and then changes them changes the vectors that are stored for for them and that helps improve performance. So this is sort of like a textbased analog of that that has a similar goal.
38:32 Yeah, you could also think about like for the third type of learning for updating the weights of a model, it's potentially helpful there to be able to forget stuff also. especially if you have kind of like conflicting knowledge and and people are starting to develop some approaches for that like unlearning is one way to do it. Okay, so those are some foundational papers about memory that were developed for assistance for agents. feedback on trajectories can be really useful. So this paper called reflection was a really impactful it's a really it's a really pretty simple but effective the way to get agents to use feedback and potentially do better. So, it's definitely worth knowing about. It's a good thing to implement if you're working on a project that might want an agent to be able to benefit from its past experiences. and the way it works is we're trying to improve the performance of an agent given multiple attempts on a particular task. So, say that you're asking the agent to like you know, search for a product on a website. It makes one attempt at it.
39:47 it says that it's finished and you're able to get some feedback about whether it was likely correct or not. So that could come from like a person looking at it. It could come from applying a model as a judge. but given that feedback, you'll want the model to try again and try to do better. And what this paper does is show that natural language feedback on the attempt can be a really helpful thing for the model to condition on in its second attempt. So like if it's trying to answer this question about what was a particular series of battles, it might just mention one particular battle and then the feedback that's given generated by a language model based on knowing this is incorrect and looking at the question and the answer might be you gave just a single battle rather than a series. So as you can imagine this would be really helpful feedback for the model to condition on as it you know does another attempt at this task and it can get it correct. and the paper shows that you know conditioning on this natural language description of what went wrong can be really helpful.
40:53 So we can generalize this also to the agent improving as it does different tasks. Right? This is improving on the same task. But you could imagine feedback might be generally helpful to improve performance on similar tasks as long as the feedback's like sufficiently general. And the final way that we can like have agents improve or you know kind of the final foundational thing for helping agents improve is remembering trajectories like entire trajectories, entire episodes that they've done in the past and using that to shape what they do on future tasks.
41:34 There is a bunch of papers that have done this. We have some links to them at the bottom of this slide. but the key thing in all of them is you'll have some collection of like training tasks and those tasks could be like a collection of demonstrations or they could be produced by the agent as it's carrying out tasks one at a time. and you'll pull all of those tasks together. Maybe you'll additionally like generate some text that describes feedback from them sort of like reflection did on the last slide. And you'll have that pool of experiences.
42:06 And then when you get a new task that comes in, you'll retrieve from this set of trajectories and maybe generated text about them to find something that's relevant for the task that you're carrying out. You'll put it in the context window of your model and it'll generally help you to do better. so this is sort of like rag for agents, right? and it's pretty effective. Any questions about this?
42:37 Yeah. >> What do you mean by trajectory in this case is like sequence of calls. >> Yeah. Yeah. So a trajectory generally for an agent is the sequence of like messages that it gets from the environment or the user. So the observations the actions that it takes like the tool calls and and potentially also you know the chains of thought that it produces. So one way to think about it is basically just like all the sequence of of messages in the context window of the model >> and you retrieve it by image differently. You can do this regular embedding retrieval or compare to process sequences and do some set comparison.
43:22 >> Yeah. What are the different ways that you could do retrieval? So typically you want the model to you're giving the model the description of a new task that it should carry out. So you have just that text description and you'll embed that with an embedding model and you'll retrieve based on the descriptions of other tasks that each have like a trajectory associated with them and maybe you'll also constrain that to be like we'll just retrieve the tasks for this particular domain that we're working in. yeah, good question. Any other questions about this approach? Generally, this is sort of like a whole class of approaches.
44:01 there's different ways to instantiate it. the details like how do you build up the experiences? How do you do the retrieval? but just want to kind of give you a sense that if we have past successful trajectories and we show those as examples to the agent, it can help it to do better. Okay. So with that we kind of have the foundation for talking about actually inducing skills. so we can think about skills as being like parts of a task that are reusable across different tasks. So at the very beginning we talked about like searching for a product and that might look something like we tell the agent show me results for this particular query and the agent might produce a chain of thought like this and then it might produce these particular actions that actually interact with the web page like clicking on this element identified by this particular ID which is the search box typing a query in there and and clicking on another element which is like the actual button to search.
45:13 And this chunk of a task might be reused on future tasks. Like if I say what is the price range for this particular item, it might need to do these same exact steps again as well as some additional ones afterwards. And so we can think of a skill as being a specific like reused part of the task. Is this a good way to represent a skill? Can anybody think of any issues with this?
45:49 >> Yeah. just >> Yeah, that's right. Yeah. So, like if the element ids on the page change, the skill will break. And you know, there's a number of ways that that could happen. Like, you know, maybe the elements are maybe it's the same page, but things are just numbered differently. You can make some changes to the action space to deal with that. I think JY will talk about that in his lecture. But like if we go to a different website that has like a different search interface it's going to break and we'll see some examples of that later on.
46:31 Yeah. So we'll generally compare as Graham said text versus code as ways to represent skills. I want to briefly highlight some really cool papers from the past that I think kind of like lay a foundation for skill induction for learning skills from experience. one is called Voyager and they're controlling an agent in Minecraft. and they're using code as a way to control the agent where the code functions implement things like crafting a particular item or combating a zombie. And representing these like subtasks as functions allows functions to call each other. So that as the agent like learns functions for simple things, it can then like compose them calling them in other functions and you can carry out increasingly complex tasks.
47:26 There's also a line of work from the program induction community that that does this. I think a really nice representative of this is work called dreamcoder and a few papers that built on it. And there you're sort of you have basically like grammarss over things that you're constructing like objects and you like have some examples of complete objects which are constructed using like very low-level functions and you search for recurrent patterns in that you find patterns that can be abstracted into functions and you do that repeatedly and you're sort of like compressing the programs that construct these objects.
48:07 And then there's also some follow-ups to this that integrate like large language models, Python code, and natural language descriptions too. And some of the same ideas in those papers are also useful for agents that are using language models to interact with the world. A typical way that we'll evaluate systems for inducing and using skills is an online learning setting. So when you're interacting with an agent, you are maybe having it carry out a bunch of tasks in succession and some of those tasks are going to be similar to each other. You want the system to be able to learn from your interactions with it and then be able to do better in the future, right? So this is an online learning setting where we'll have tasks come in one at a time. So for example, like you might say, add a Sony Bluetooth headphone to my wish list. And we'll be building up a memory of skills incrementally as we solve those tasks. So there will be an induction step that we'll talk about in a slide or two. And that induction step will create a skill like search for a product and add a product to the wish list that are useful for solving this particular task.
49:26 And you know maybe we have another one like this task here and we can apply those skills on future tasks like this task might also involve searching for a product and hopefully we'll do better on that task given that we had this skill induced from the previous task and so on. So what we're interested in is if we can measure success on each of these tasks, is our success rate like getting better and better? Are we able to solve increasingly complex tasks as we're learning from experience and building up representations of the ways to do these simpler tasks? Any questions about this setting?
50:11 Okay, cool. So the papers that we'll look at for the rest of the lecture look at sort of different parts of this space of learning skills from experience having this library and ask questions about what should we do with the skills like after we've induced them. So there's generally like a learning step where we'll have these tasks coming in. We'll try to get a skill out of them. will decide whether to store that skill in the memory that we're building up over time. There's the step of like actually using this memory of skills to potentially improve performance on the tasks that we're carrying out. And then finally, we might want to, you know, if we're getting too many skills, we might want to try to simplify those, like delete the ones that aren't being used, or if they're too specific, we might want to make them more general. or like consolidate and merge multiple things together.
51:14 We'll go a little bit deeper into one paper that I think is pretty representative of ways for inducing skills. it was also done here at CMU as work led by Zora Wong who will be giving a guest lecture on some other topics a little bit later on in the course. but this paper's called agent workflow memory and the way it works is it we applied it to web tasks. this is work with with Graham also and me and we applied this to web tasks and you have a query like this and you know tell me the number of reviews that our store received so far and when the agent's carrying this out these are the actual tool calls that it'll produce.
51:59 So we have this sequence of tool calls and we want to try to identify which parts of this might be potentially reusable in the future and you can probably guess how we do this. We ask a language model to take a look at the sequence of tool calls and identify ones that seem like they might be useful on future tasks. And we'll have the model output what we call workflows which are sort of like a textbased representation of skills text and actions. And a workflow will have like a description of the subtask like searching for a particular item.
52:37 And then it'll have the sequence of actions that you use to do that. And we're having the model make this a little bit more general so that it could apply to like searching for other terms. So we have it use like create a template that can abstract out some parts of the initial action sequence. You might be thinking like this is starting to look like code, right? That's true. and a little bit later on we'll compare code to this also and show how that can be better in some ways but also make things a little bit more fragile.
53:14 A pretty important part of this is we'll apply a judge model to this trajectory to decide have the judge predict whether the trajectory seem to be correct or not. And we'll use that to determine whether we should actually add the workflows that were induced to the memory. because we don't want to be remembering things that were incorrect because those might steer the model wrong in the future. >> Any questions about this?
53:47 Okay. And so the way that we'll give the model access to these collection of workflows is just by sticking them in the context window of the model. So this looks a lot like you know this agent skill standard. you have choices about whether you show everything or whether you show just you know kind of the text description. and what you do there could depend on how many skills you have and you know the context length of the model.
54:20 So for the sake of time I I'll skip over this induction prompt but we do find that having this memory of like past subtasks can help to improve the performance of the agent as it's learning online. So on the x-axis here we have like different tasks in a fixed ordering from this benchmark involving interacting with like a map tool and the blue line here is the baseline agent that doesn't have a memory that sort of converges to around you know like 10% accuracy on these tasks and the labels here are the tasks that are being solved by the agent correctly. and then this black line which adds in this memory of subtasks improves pretty substantially and it's able to you know this gap emerges between the two but it's also able to carry out these like increasingly complex tasks eventually doing things like you know finding a hotel near this location showing me the walking path that the baseline agent just isn't able to do.
55:25 So this is using, you know, sort of this mix of text and example actions to represent skills. But we could also consider using code, right? And both of these are implementations of a search product function. And if we're using just this text and examples, this is going to be in the context window of the model. and then it's going to be needing to produce these tool calls in a new context, right? As it tries to carry out the same subtask. So, it's flexible like the model could choose to insert a particular search term to search for a different product. If the website has changed and we no longer have like this particular element for the search box, then the agent could choose to use the correct one instead. but it also means that the agent needs to like actually produce all of those tool calls itself. If we're using code, the agent could actually just call this function as a tool, right? If it passes in the right arguments and if the functions correct, then it doesn't have to do anything. It doesn't have to produce all of those low-level actions itself.
56:36 the tool will just do that as it executes in the environment. Can anybody think of some pros and cons of using a function like this as a representation for a skill? Any cons? >> It's very rigid. >> Yeah, it is very rigid. So like the model will need to the model calling this tool will do exactly these three steps and there's no room to to deviate from it. yes that's a main call that's a main like con to it but we also get a lot of the pros of using code right so like we can nest functions it can be hierarchical we can actually like generate test cases for that specific function too independent from the entire trajectory that it's executed in. And we can do things like you know refactoring also.
57:37 So Zora has another paper called inducing programmatic skills or agent skill induction which which do this and it looks pretty similar to the approach we were using to induce these textual workflows. So you have a trajectory like this with these tool calls and we'll have the language model we'll we'll just use the fact that language models are also good at generating code and we'll prompt the model to generate functions which abstract a lot of the behaviors in this trajectory and these are real examples. So the language model will write this search reviews function and a doc string for it and then you know it has these low-level tool calls as lines in the function. This other one for open marketing reviews but we'll also have it generate sort of a rewrite of this original trajectory that uses those tools. So a really nice thing about code is that we can test it by executing it. So instead of applying the judge to the original trajectory like we did before, we can have the language model. Well, we can execute this generated abstracted code and then apply the judge to the end result that you get from that. And if that appears to be correct, that's sort of like a stronger indicator that the skills, these code skills that you induced are also correct.
59:00 And if they are, then we put them in the memory and they become usable to the language model just as tools. So this is a way of like building up a tool library that the model's able to use on future examples and we show that it also you know improves performance. Any questions about that? Yeah. So a nice thing about code skills is that they allow testing just of the skill by itself. there's this nice paper called skillw weaver which does this. so this is sort of some pseudo code for the the loop that I just showed you where you have a task, you propose some set of like code skills for it and then you'll try to use those skills to execute the task. You'll get an episode, you'll apply a reward model to it. and if it succeeds, then you can put all those induced skills into your memory. But if not, then you could make some revisions to it. And there's a number of ways that skills might not succeed, right? So, one thing we could do is like apply a code llinter to an induced skill. So, here's a real example from the paper.
60:17 There's this induced skill called identify pill. you know, for like interacting with a drug website. And this function like takes a lot of arguments like you know the the make of the pill the color but in the initial version of this skill that the agent wrote it actually didn't use all the parameters. So like it ignored this color parameter. So you could get feedback from a llinter on this skill and then sort of in the reflection type way condition on that and then like you know create an updated version of the function and store that or like try executing that and store that. You could also use feedback from this reward model and condition on that when you're making these revisions to the skill 2.
61:02 So these are some nice benefits of code that can be advantages even if you know the actual code function itself is a bit more rigid. Another nice benefit is that because these functions that are induced are now tool calls, it can really reduce the number of times that your agent needs to interact with the environment. So here's an example from Zora's ASI paper. We have this task like updating a couple addresses on a page and for the base agent you have to you know like do all the very low-level actions of navigating through all these forms typing the particular things from the address. But if we have this model that has induced these code skills, you can and this is a real example from from the work where we induce this navigate to address settings and update address details functions. We can actually solve this task in three steps where we you know assuming that this is a good fit for the site. we can just call these two functions and complete the task.
62:12 and the agent is actually much faster because it doesn't need to reobserve the website and then generate the tool call, then reobserve the new website, generate the new tool call. as you'll probably see in the guey lecture that JY is giving, a really big bottleneck for these models is actually the number of times that they have to interact with the site because these images take up a lot of tokens and actually producing a chain of thought before each action takes up a lot of tokens too. All of those have to be generated. So efficiency is really important here.
62:48 And in this work we did find so we did a controlled comparison between using text skills and code skills. This was on a set of tasks which did have sort of more repeated structure. but we found that in comparison to no memory text skills helped but code skills helped even more in terms of you know the accuracy of the system but also we got pretty big improvements in efficiency the number of times that the agent needed to interact with the page.
63:18 Cool. So, as we've kind of talked about before, a big potential issue with skills is that they might not be general. And here's a failure case of this approach and actually a failure case of these code skills. So, we tried to see how well could skills generalize across websites. And we induced these code skills on one site and then we tried to apply them on a real website like the Target shopping site. So this skill that was induced on a different site worked on that site but like uses assumes that this this particular element that you're interacting with has a drop down like this. Whereas on the target site it's you know this set of radio buttons and so it it fails there. And you have to have the model be able to like actually edit the skill based on feedback from the environment as it's interacting with it.
64:20 But code has a solution to this, right? so we have abstract classes and those can be instantiated in different ways. There's this paper called poly skill which does this. So they're using code as the representation sort of building on this ASI work that we did. but the first time that the model interacts with a new website, it writes an abstract class which doesn't have implementations for the methods, but could have stubs like searching for a product, adding to a cart, checking out.
64:53 And then it'll also write a website specific implementation of it like this one for Amazon. Then when it's interacting with a different site, you could have some metadata or you could even just have the language model trigger that this particular concrete implementation no longer applies. and then you'll write a different instantiation of the abstract class. And they show that this helps too. this is also nice because it gives you a way to have like a large number of specific skills, but only have a subset of them be active at a given time that are actually relevant. So, this kind of makes sense, right? It's, you know, just a software engineering best practice that's also applied to agents.
65:35 Okay. yeah, we talked about all this already. you guys had a good sense of the the pros and cons of each of these types of representation, but it's helpful to know that, you know, the skills standard allows you to combine both and there's a lot of research to be done on the best way to combine these representations together. like said, okay, so we'll go quickly through a few papers on different kind of like parts of this skill life cycle. This is a really open research topic of like what are the best ways to induce and manage these skills. you'll have the papers for for more details. but you can also explore this in your projects towards the end of the lecture or the end of the class if you're interested.
66:22 Everything we've talked about so far has been learning from success, but it's also potentially pretty helpful to learn from failures. So say that the model like tries to carry out this task like you know searching for Bluetooth headphones. but for this particular website they sort of have like their search terms are or rather than and so you get a list of everything that's Bluetooth or headphones or a Sony. This is a real example from this reasoning bench paper from Google. So you get like 5,000 results and the agent just breaks on this like it has to pagionate through all of these 5,000 results. it does, you know, it loses track of what the task is and it fails. But if we observe that failed trajectory sort of in the reflection style way, we could produce some text that gives guidance on how to avoid it in the future. Like saying we should give a more specific search term rather than this more general one and we should you know have like a larger number of items displayed so the model gets more in its context window at once. And this paper generally uses the same framework as agent workflow memory, agent skill induction, but instead of just having these kind of abstractions of the correct trajectories, it generates this text feedback which is applicable to failed trajectories too and is also you know the kind of thing that you would write in a skill yourself if you were writing one and they find that this is pretty helpful. So these are different like types of memory. so synapse uses trajectories like full trajectories with all of the actions and observations all the tool calls and messages. this is agent workflow memory that uses these slightly abstracted parts of trajectories. And this is their approach that uses these text descriptions of strategies and adding and negatives going you know adding and negative examples as inputs to the memory. doesn't improve performance when you're using either trajectories or workflows, but does improve substantially when you have sort of these text descriptions, which kind of makes sense given the example we saw before because you can describe in a general way how not to fail rather than remembering and conditioning on those failures.
68:50 Another important thing to think about is we're deciding whether to store trajectories you know store things in the memory or what type of strategies to infer from the examples based on whether we judged the example to be successful or not. That's in most of this work using a model as a judge that looks at the final state of the trajectory, looks at the task that you were trying to solve and predicts does it seem like I got it correct or not. So a really good question to ask here is what you know how much does the quality of that judge affect the performance of the algorithm because we know the judges aren't perfect. this paper reasoning bank controlled for this. So they run their methods with a perfect judge.
69:39 and they also like to so they use kind of the ground truth knowledge of whether it succeeded or not. but then they add some noise into that and so you're able to control the accuracy the simulated accuracy of judging this trajectory and the performance does fall off but they find there's kind of a sweet spot where you do get improvements from the memory and there's sort of a widish range of accuracies where using the judge to induce the memory is helpful but there's definitely room to do future work here.
70:19 Okay. And yeah, with the last few minutes, I want to come back to we had a question before about does having more skills than are necessary potentially hurt performance? And we also had a question about like we're if we're retrieving skills from a set does that retriever matter? Like does the quality of that retriever matter? So there were some nice ablation experiments in this reasoning bank paper that control how many experiences you are retrieving from the memory that you have and they show that performance does fall out fall off as you have more available. so this could be because of a couple different factors. So you know maybe you just haven't run your agent on that many tasks and maybe there's nothing relevant in your memory.
71:17 So putting more stuff in is just bound to be irrelevant. That would be sort of like just a fundamental limitation of this approach applied in that setting. Right? You can only learn if there's some similarities between the things you're learning from and the things you're applying to. But it could also be like a limitation of the model itself. Maybe the model gets thrown off by having more things available in the context window. That could potentially be fixed by training the model, right?
71:45 To be better at not being distracted by irrelevant context, to be better at reasoning about what's actually relevant. And yeah, it can also potentially be useful to explicitly reduce the size of your memory so that there's less of a burden on the language model to select from the things that are in it. And we did some work on this that sort of uses like a caching type approach that you just look and see how often has a particular item in your memory been used in the past and if it hasn't been used very frequently, you'll drop it.
72:26 And this can you know improve this efficiency of the approaches quite a bit because you don't have to put as much in your context window but can also improve their success if the models are getting distracted by things that are irrelevant. Yeah. And the very last thing that we'll cover is so all of this was in some ways a little bit ad hoc, right? Like we were just having the language model look at these past experiences and then produce a skill which would be put in the memory and used in the future. But we're just like prompting the language model to predict things that seem like they might be useful in the future. And a really natural question is could you just train the language model to do that directly?
73:08 you can. this is a direction that's starting to be explored just really recently. So these papers are just appearing at you know just appeared at ACL this year. But the basic idea here is that we're going to do reinforcement learning over multiple tasks seen in sequence. So this online learning setting that we've been covering for evaluation, we're also going to run training on it. We'll get multiple similar tasks in sequence and we'll be building up the memory. in the same way that we've been doing before by inducing skills from the experience and using the memory on the future tasks. So this is a very complex, you know, process, right? Like we're using a couple different models here.
73:53 we're storing things in a memory. We're retrieving those. We're using them. But the good thing is reinforcement learning doesn't care. You can just apply reinforcement learning to complex non-ifferiable processes like this. We'll have a couple lectures that show you how. and you can get reward from did this second task succeed and did it use tasks that were induced in the past. So you can just do reinforcement learning on this reward being trained on skill induction on sequences of similar tasks. And there's a couple papers that have explored this. They both find that this is helpful. And one of them had this interesting result that it helps to improve success if you also include this reward term that incentivizes reuse of the skills. So you could also imagine like introducing other sorts of reward terms that like minimize the size of the skill libraries that you've induced to try to you know kind of keep things regularized and not overfit too much. I think there's a lot of interesting like feature work that could be explored here.
75:03 And yeah that's that's all the time that we have. but hopefully you got a sense for the way that skills are induced and also written. you'll apply those in your projects and you can explore them in the research projects too. I'll stick around for a few minutes if folks have any questions.
Summary
- Agents can retain information beyond their context window to improve future task performance through external memory systems.
- Skills can be human-written or induced from past experiences, serving as reusable knowledge for agents.
- Memory management involves determining what to store, update, or delete based on the agent's experiences and task requirements.
- The lecture outlines different methods for agents to update their memory, including context windows, external databases, and model weight adjustments.
- Evaluating the effectiveness of skills is crucial, as too many irrelevant skills can hinder performance.
- The use of code for representing skills allows for more structured and testable implementations compared to text-based skills.
- Learning from both successes and failures can enhance the agent's ability to perform tasks effectively.
- Reinforcement learning can be applied to optimize the skill induction process, improving the agent's performance over time.
Questions Answered
What is the focus of today's lecture?
The lecture focuses on how agents can store information across tasks in external stores to improve future performance, emphasizing skill induction and the complementary nature of skills and instructions.
How are skills structured for agents?
Skills are implemented as collections of files, including a mandatory skill.md file that contains metadata and detailed instructions for the agent on how to apply the skill.
Why is it important to base skills on past experiences?
Basing skills on past interactions leads to better performance, as agents can learn from previous tasks rather than relying solely on initial task descriptions.
What are the potential issues with representing skills?
Skills may break if the underlying elements change, such as when element IDs on a page are modified, highlighting the need for adaptable skill representations.
What advantages does using code provide for skill induction?
Using code allows for more structured skills, reduces the need for frequent environmental interactions, and enables the agent to execute tasks more efficiently.